All posts

Local AI 8 posts

Every post filed under Local AI, newest first.

Apple's new Mac mini is pitching itself as an always-on agent box
6 min read

Apple's new Mac mini is pitching itself…

The M6 Mac mini starts at $899 with up to 4x faster on-device AI than M4, 64GB unified memory on M5 Pro, and Thunderbolt clustering for larger local models. Apple is finally naming the use case developers already bought it for.
DiffusionGemma hits ~1,500 TPS on one H100: when a diffusion LLM beats autoregressive serving
8 min read

DiffusionGemma hits ~1,500 TPS on one H100:…

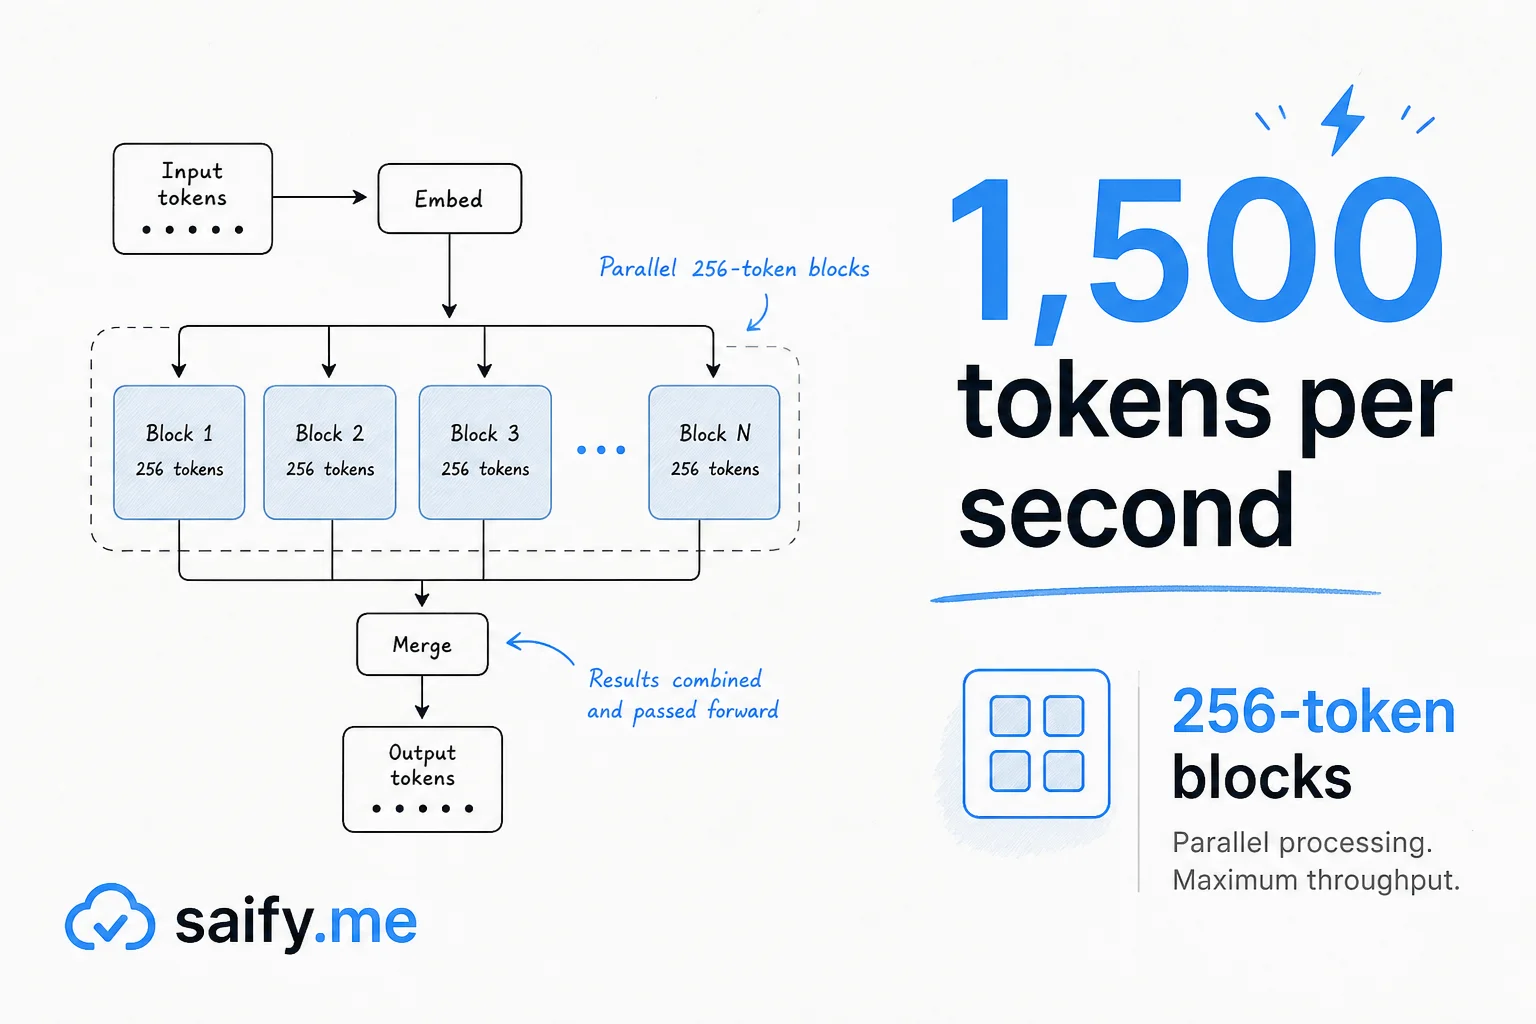
Google's open-weight DiffusionGemma denoises 256-token blocks in about 12 passes, reaching roughly 1,500 output tokens per second on a single H100 at batch size 1. Here is where that speed matters, what you trade away, and how to serve it with vLLM.

Unsloth’s Dynamic GGUFs make Gemma 4 12B fit on a laptop
5 min read

Unsloth’s Dynamic GGUFs make Gemma 4 12B…

Google’s Gemma 4 12B is multimodal with a 256K context window. Unsloth’s Dynamic GGUFs squeeze a usable 4-bit build into roughly 8GB of memory without throwing quality off a cliff.

Krea 2 shrinks to 12GB so consumer GPUs can run aesthetic image gen
4 min read

Krea 2 shrinks to 12GB so consumer…

Krea AI open-sourced Krea 2, a 12.9B-parameter diffusion transformer trained from scratch. Turbo runs in 8 steps on GGUF quants that fit 12GB VRAM. Raw is the fine-tune base; Turbo is what you ship.