5 min read
vLLM + Mooncake share KV cache across…
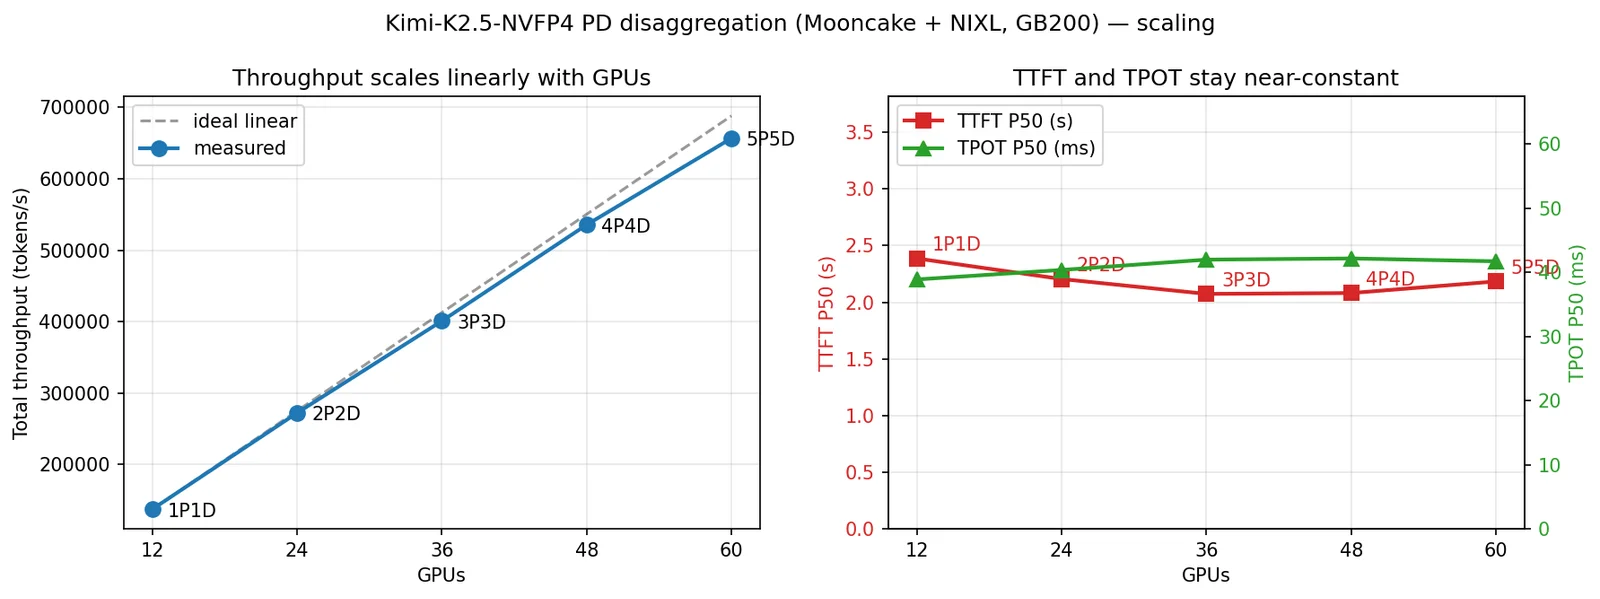
Agent traces reuse huge prefixes turn after turn. Mooncake Store gives vLLM a distributed KV pool: 3.8x throughput, 46x lower TTFT, and near-linear scale on GB200 clusters in vLLM’s report.
Agent traces reuse huge prefixes turn after turn. Mooncake Store gives vLLM a distributed KV pool: 3.8x throughput, 46x lower TTFT, and near-linear scale on GB200 clusters in vLLM’s report.