Blog 385 posts
Notes from the trenches on AI engineering, LLM apps, and the full-stack work that holds it all together.
Claude Managed Agents now run on cron schedules and pull API keys from vaults the model never sees. Here is what shipped, how vault injection works, and when I would retire my own scheduler.
A Meta-Stanford-Illinois survey argues agents reason inside executable harnesses, not raw text. Plus Meta-Harness shows how to search that code automatically.
Cohere's 30B MoE North Mini Code runs on a single H100 with Apache 2.0 weights. Strong SWE-Bench numbers, 2.8x throughput, and a verbosity tax you should measure before you swap APIs.
Anthropic's Fable 5 tops CursorBench at 72.9% but costs about twice Opus 5. Here is when I route hard agentic work to Fable and when I keep Composer on the loop.
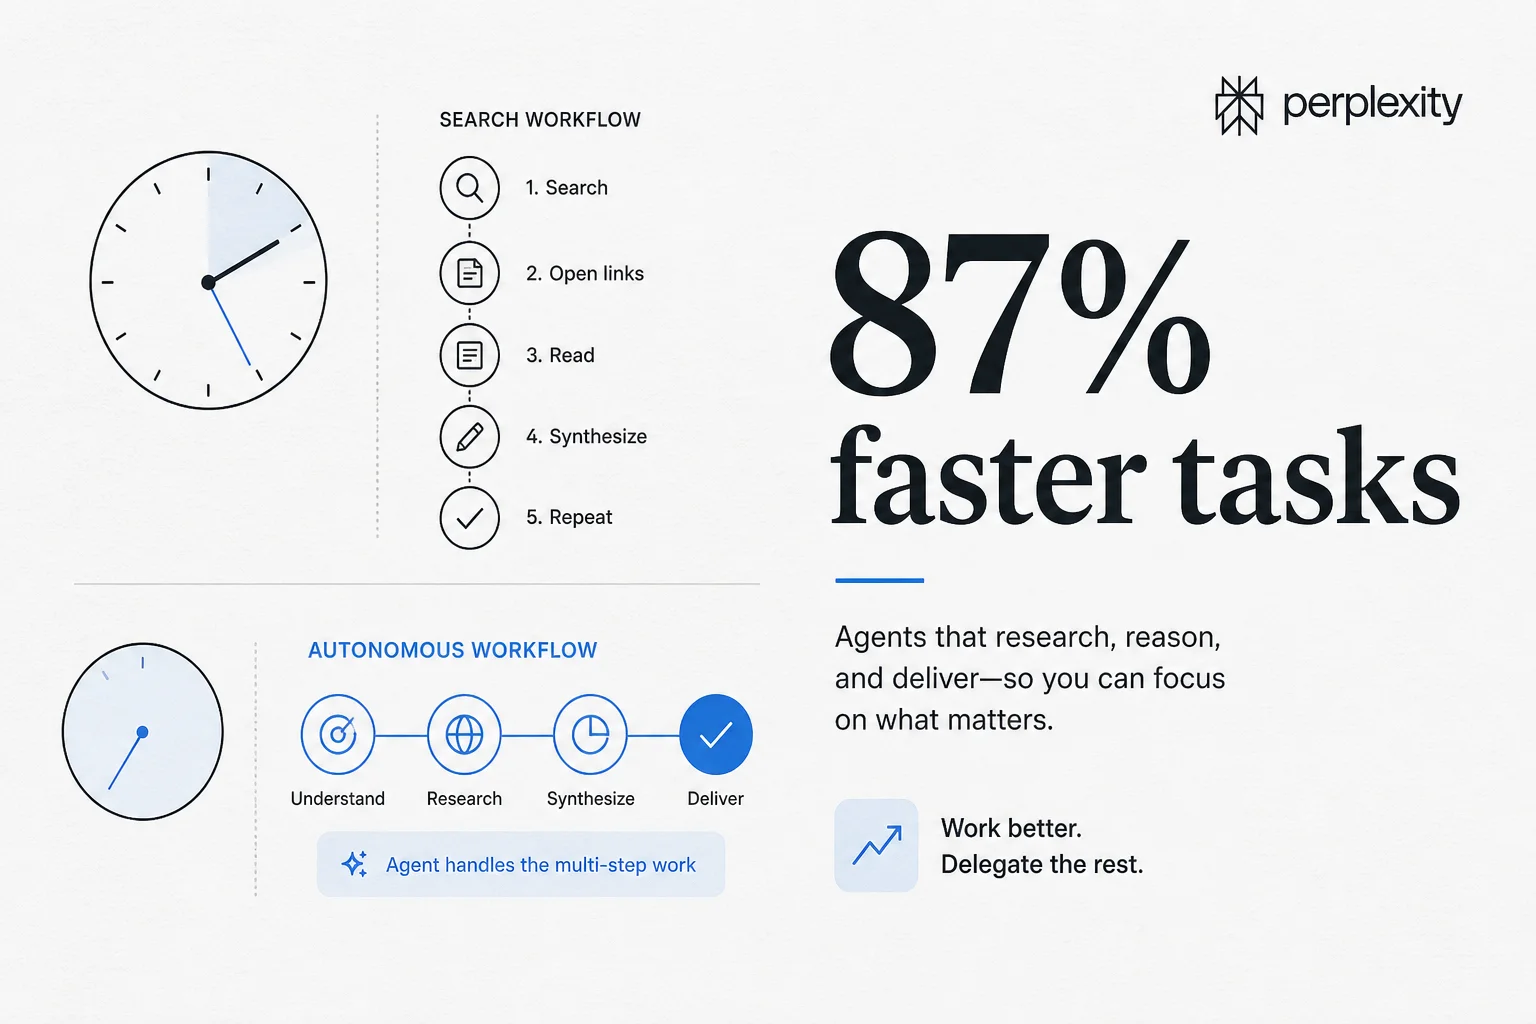
A June 2026 Harvard Business School study with Perplexity finds Computer agents finish near-identical tasks in 36 minutes versus 269 with search alone. Here is what the matched pairs actually show.
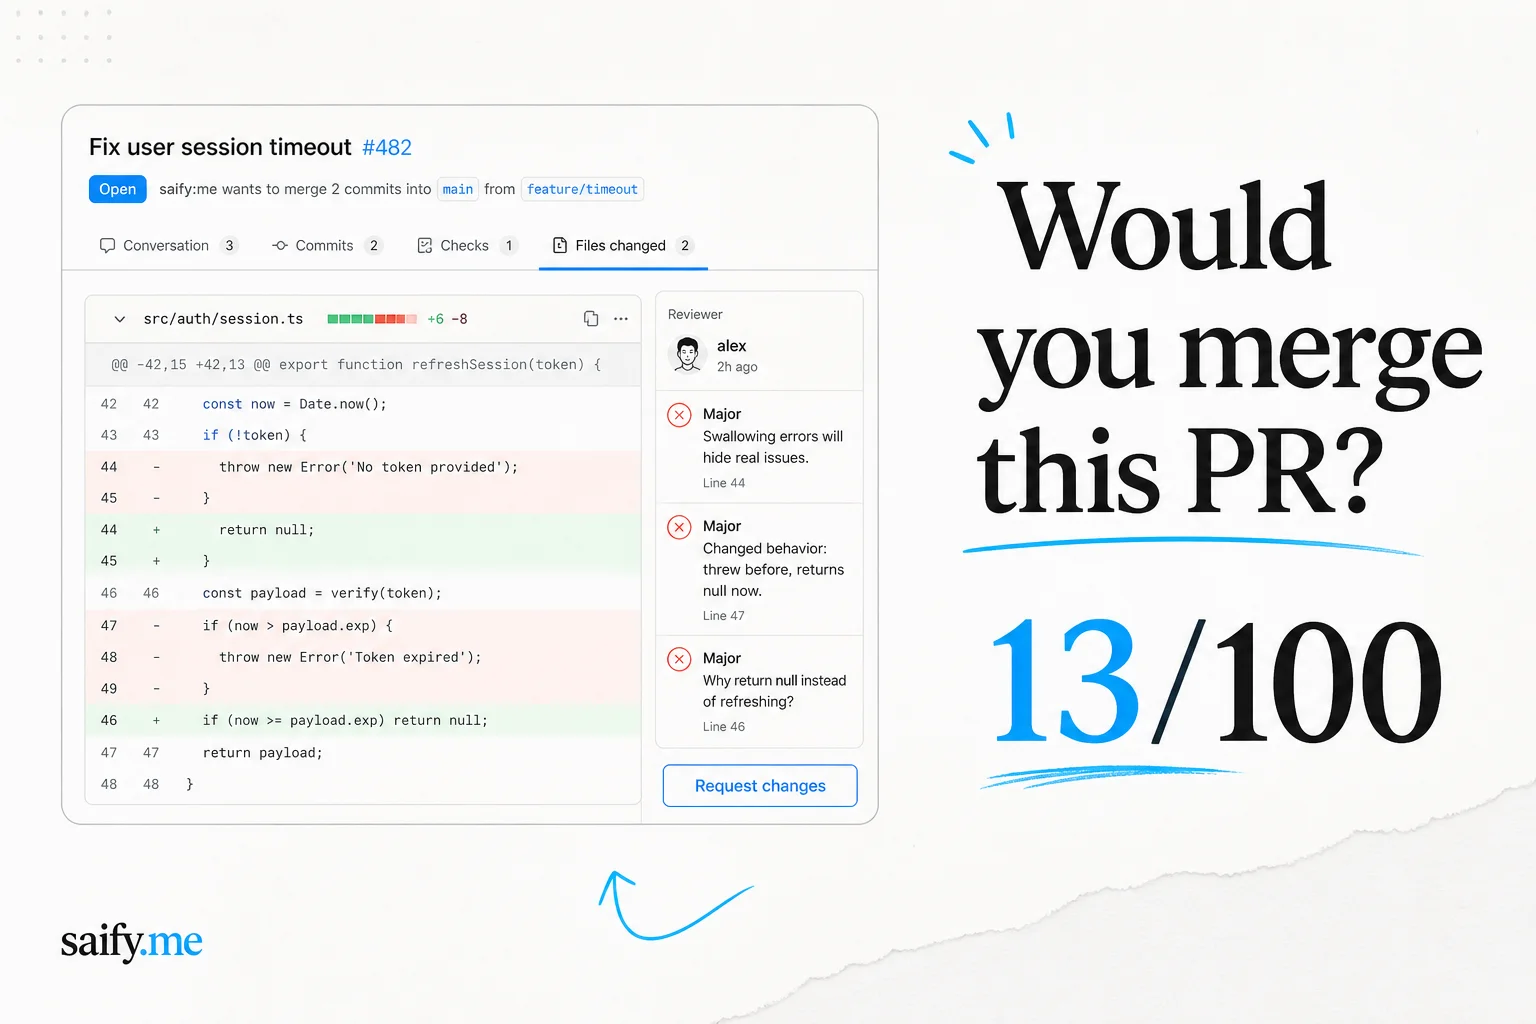
Cognition's FrontierCode benchmark grades mergeability, not just test passes. On the hardest Diamond tier, Claude Opus 4.8 leads at 13.4%. Here is how I read that number for production agent routing.
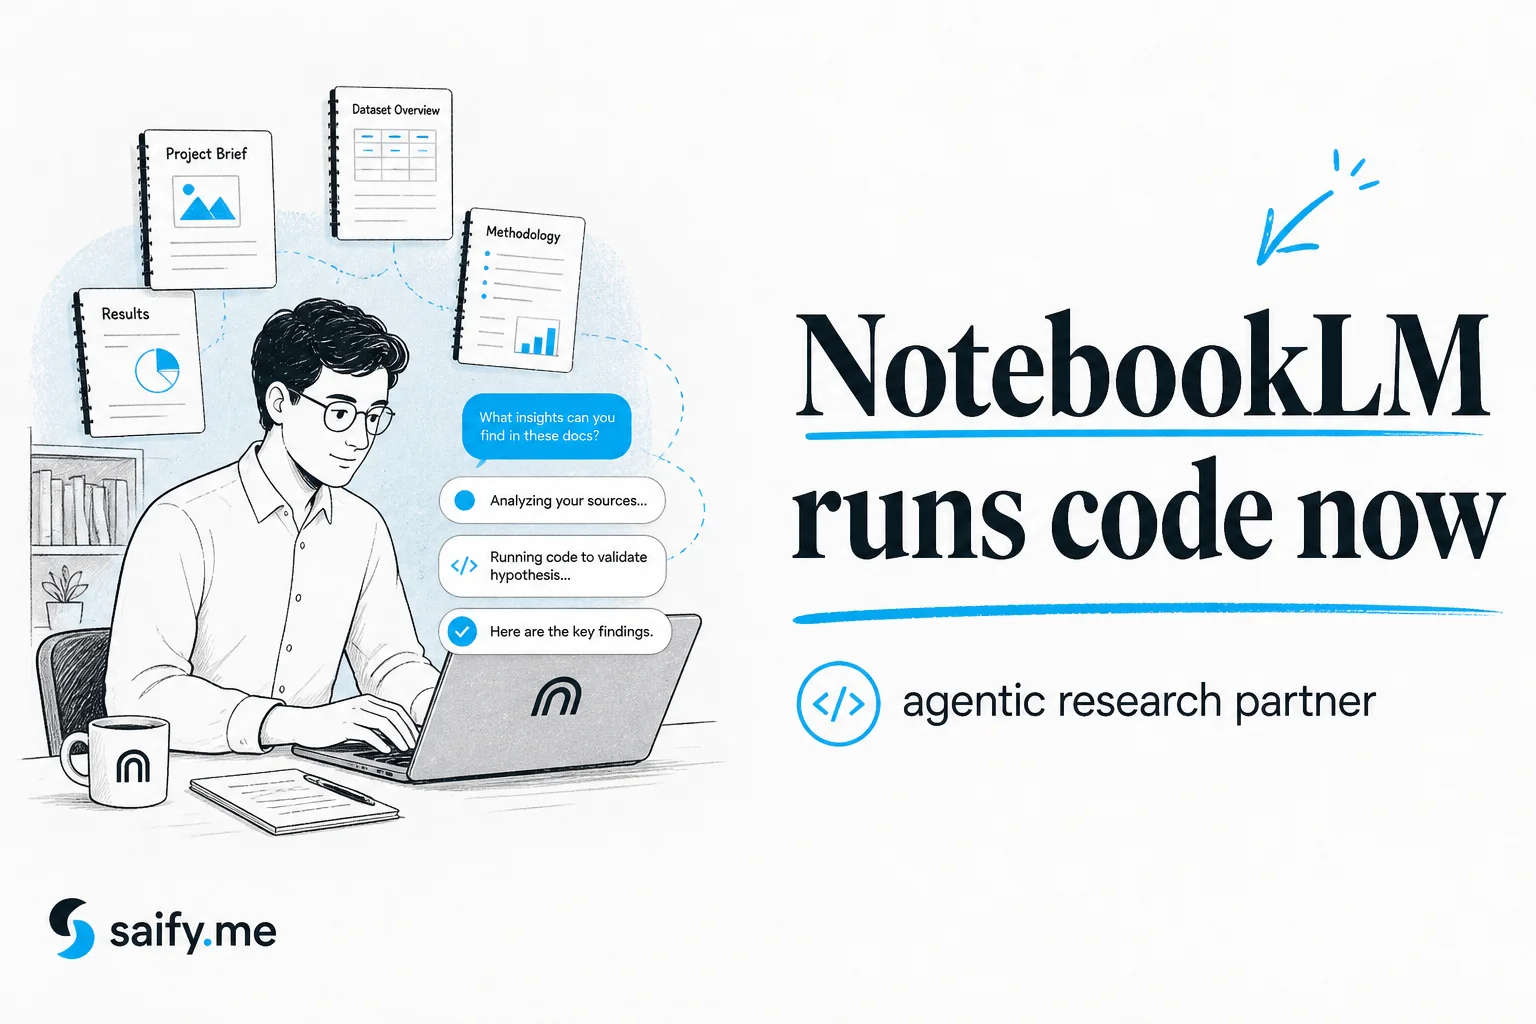
Google upgraded NotebookLM on June 8, 2026 with Gemini 3.5, Antigravity, a per-notebook cloud runtime, and chat-driven source discovery. Here is what changes for research workflows I actually run.
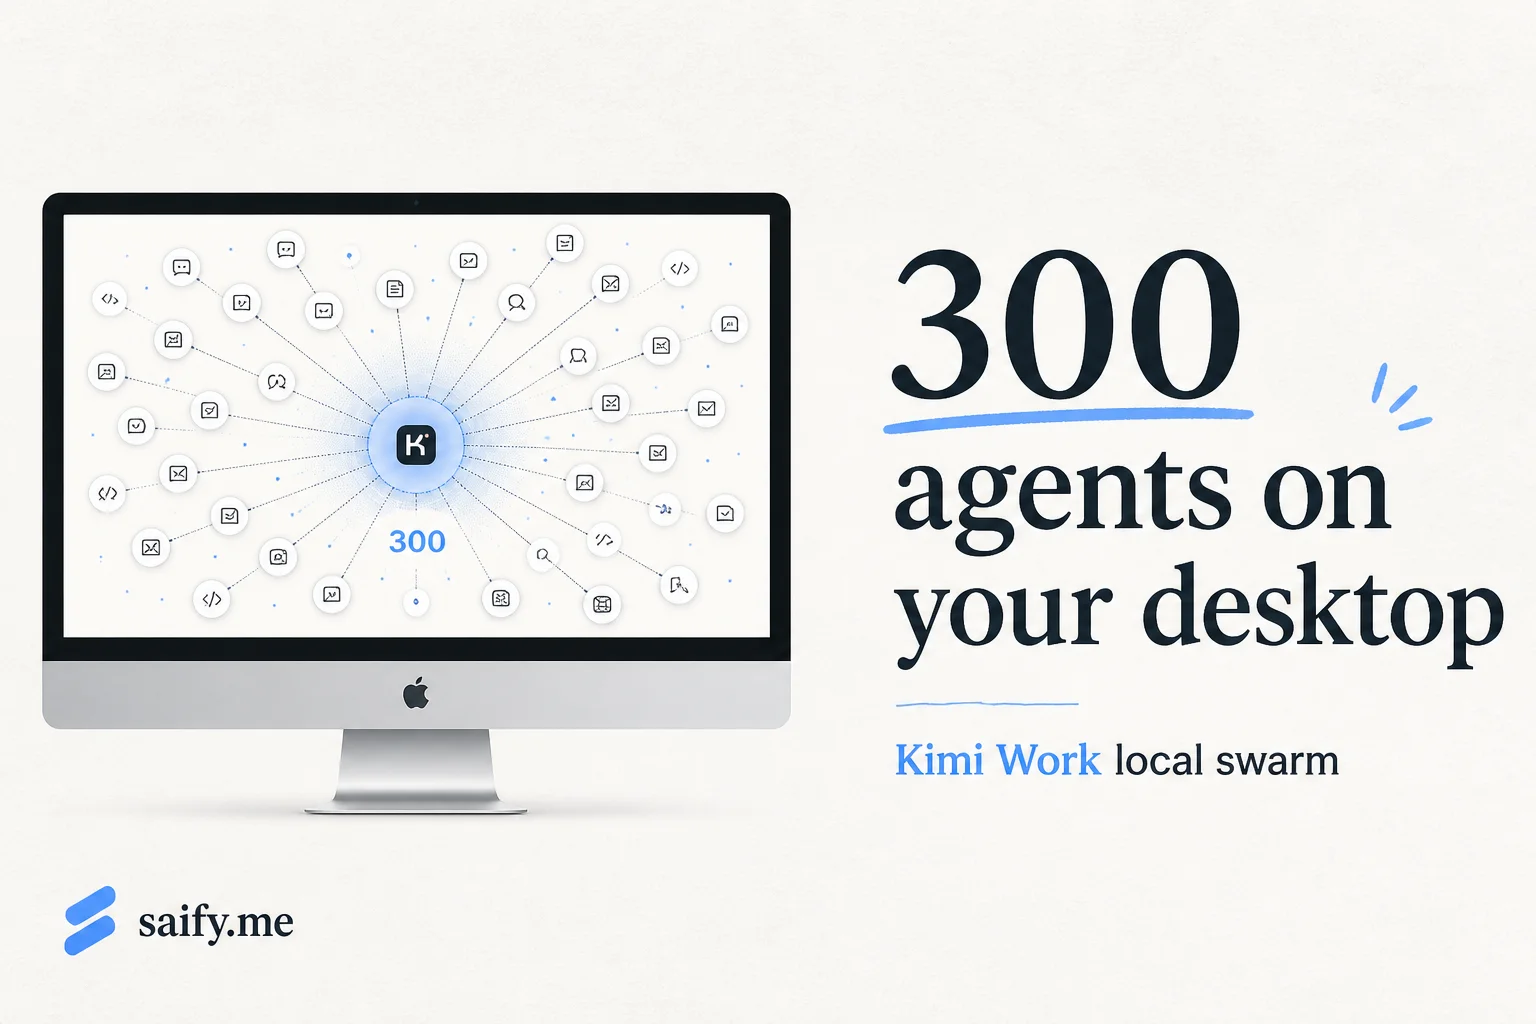
Moonshot's Kimi Work desktop agent reads local files, drives your real browser, and spins up to 300 sub-agents per task. Here is how Agent Swarm compares to cloud-only coding agents I deploy for clients.