Blog 385 posts
Notes from the trenches on AI engineering, LLM apps, and the full-stack work that holds it all together.
FastContext is a 4B–30B exploration subagent that returns file-line citations instead of dumping whole files into the main agent. Mini-SWE-Agent gains up to 5.5% success with up to 60% fewer main-agent tokens.
WeiboAI's MIT-licensed VibeThinker-3B scores 94.3 on AIME26 and 96.1% on post-cutoff LeetCode contests. It trails frontier models on knowledge-heavy GPQA by design, not by accident.
Anthropic disabled Claude Fable 5 and Mythos 5 globally on June 12 after a US export control order. Here is what broke, what stayed up, and how I diversify model providers before the next directive.
Z.ai's GLM-5.2 brings a 1M-token context window, IndexShare sparse attention, and MIT-licensed weights. One day after the Fable 5 export control shock, open long-horizon coding got a lot more interesting.
Moonshot's open-weight Kimi K2.7 Code keeps the 1T MoE backbone but cuts thinking tokens ~30% versus K2.6 while jumping +21.8% on Kimi Code Bench v2. Here is when I would route agents to it.
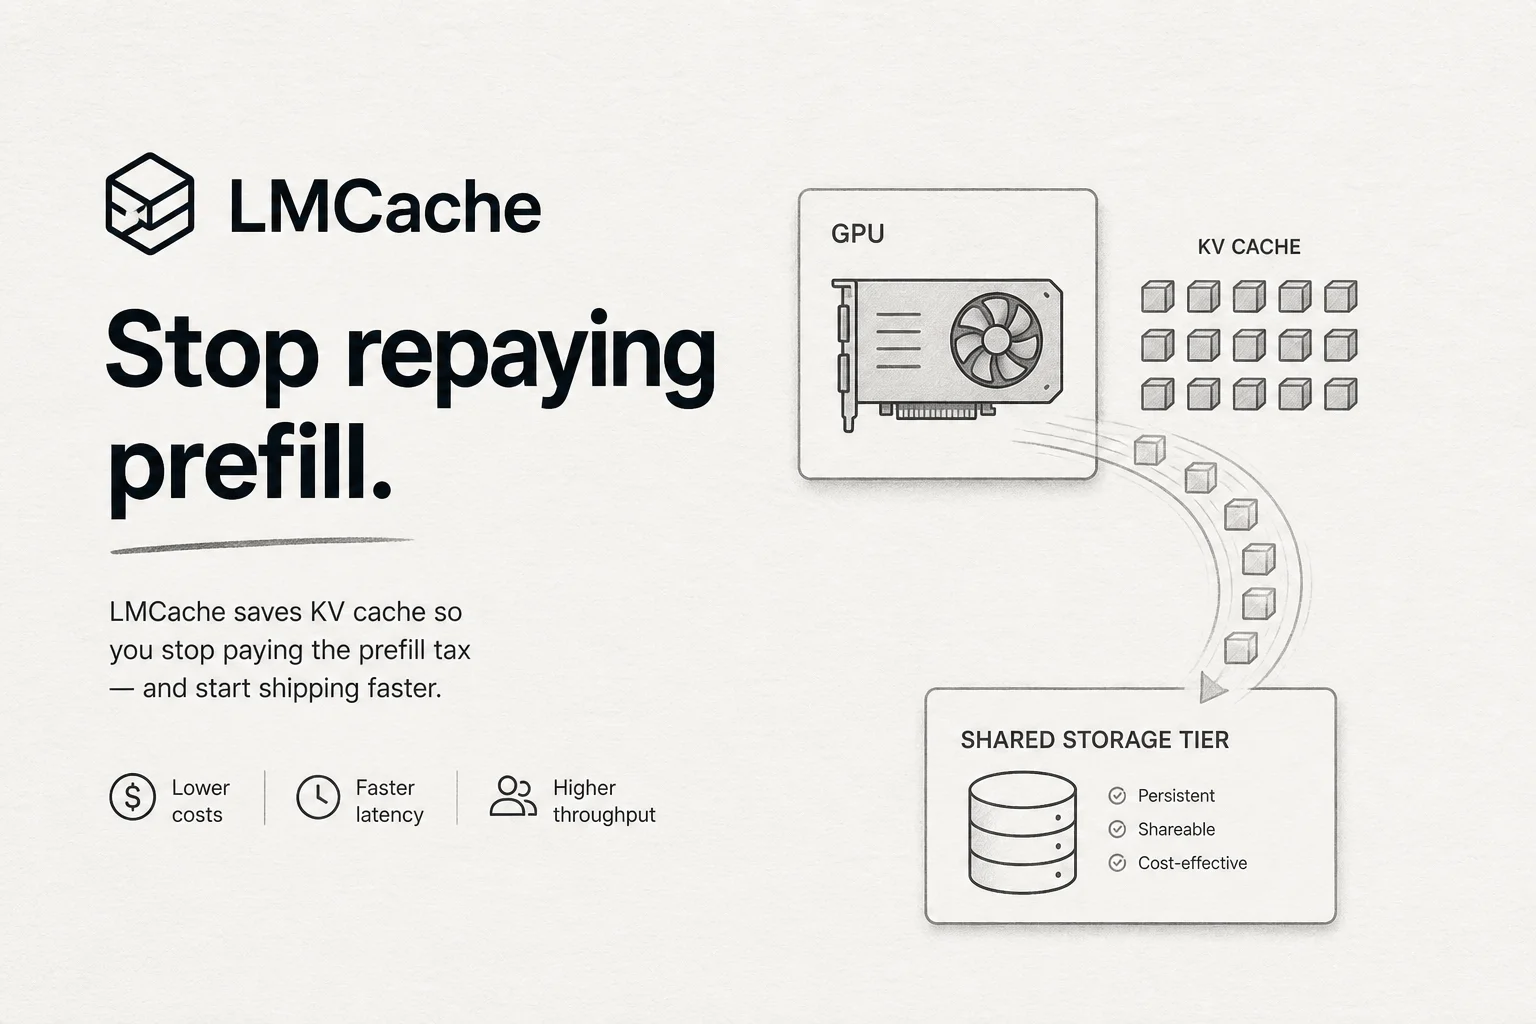
LMCache is an open Apache-2.0 KV cache layer for vLLM and SGLang that offloads and reuses prefixes across queries and engines. Reports cite up to 15x throughput and 3–10x TTFT wins on agentic workloads.
A $965B confidential S-1, OpenAI's 'chat is dead' pivot, and a half-trillion-dollar chip rout, all in one week. One capital cycle, one market that can't decide what to believe.
A near-complete Claude Fable 5 product prompt surfaced on GitHub in June 2026. The Mythos tier, artifact storage API, and model-switch rules are the parts that matter for builders.